Graph relations in Neo4j – simple load example

In preparation for a post about doing graph analytics in Neo4j (paralleling SPARQLverse from this earlier post), I had to learn to load text/CSV data into Neo.  This post just shows the steps I took to load nodes and then establish edges/relationships in the database.

My head hurt trying to find a simple example of loading the data I had used in my earlier example but this was because I was new to the Cypher language.  I was getting really hung up on previewing the data in the Neo4j visualiser and finding that all my nodes had only ID numbers was really confusing me.  I had thought it wasn’t loading my name properties or something when it was really just a visualisation setting (more on that another time).  Anyway, enough distractions…

Graph Data File – Simple Graph Relations Example

I took my earlier sample data and dumbed it down to fit the normal paradigm of Neo4j – separate nodes and edges load files.  I appreciated working with triples before as I didn’t have to pre-load all the nodes first, but that’s also a story for another day.

First, the nodes file looked like the following.  Note, I thought I had to add the ID though I didn’t end up using it after all:

id,name
1,Chong
2,Lashaun
3,Roberta
4,Elin
5,Tameka
6,Rosalie
7,Noella
8,Elim
9,Mae
10,Fernando
11,Alan
12,Katrina
13,Kaitlyn
14,Zackary
15,Nana
16,Lamonica
17,Meggan
18,Fermina
19,Genevieve
20,Manual
21,Jolie

The second file was simply a list of “source” and “target” names – the graph relations – where the first person had the second person for a friend.  (We handle them as unidirectional in this example.)

source,target
Chong,Lashaun
Chong,Roberta
Chong,Elin
Chong,Tameka
Chong,Rosalie
Chong,Noella
Lashaun,Roberta
Lashaun,Elin
Lashaun,Tameka
Roberta,Elin
Roberta,Tameka
Roberta,Rosalie
Roberta,Noella
Elim,Tameka
Elim,Rosalie
Elim,Noella
Elim,Mae
Elim,Fernando
Elim,Alan
Tameka,Katrina
Tameka,Kaitlyn
Rosalie,Alan
Noella,Katrina
Mae,Kaitlyn
Mae,Zackary
Mae,Nana
Mae,Lamonica
Fernando,Meggan
Fernando,Fermina
Fernando,Genevieve
Fernando,Manual
Fernando,Jolie
Fernando,Chong
Alan,Lashaun
Alan,Roberta
Alan,Elin
Katrina,Tameka
Katrina,Rosalie
Kaitlyn,Noella
Zackary,Fernando
Zackary,Alan
Nana,Katrina
Nana,Kaitlyn
Nana,Zackary
Lamonica,Zackary
Lamonica,Fernando
Meggan,Zackary
Meggan,Fernando
Meggan,Jolie
Fermina,Fernando
Fermina,Jolie
Fermina,Chong
Genevieve,Lashaun
Genevieve,Roberta
Manual,Elin
Manual,Tameka
Jolie,Rosalie

Graph of first load test of Neo4j
Basic load example of a handful of relationships.

Loading CSV Relationships into Neo4j

To get the data into Neo4j I had to run two commands.  But first I run a sort of “delete all” as I was doing lots of testing:

MATCH (n)
WITH n LIMIT 10000
OPTIONAL MATCH (n)-[r]->()
DELETE n,r;

Then load all the nodes, assigning each one to a Person entity and grabbing only the name property from the CSV:

LOAD CSV WITH HEADERS FROM "file:///Users/tyler/graph/friends_nodes.csv" AS nodes
CREATE (p:Person { name: nodes.name })

And finally, load the edges/relationships to map persons -> to persons via a has_friend relationship:

LOAD CSV WITH HEADERS FROM "file:///Users/tyler/graph/friends_edges.csv" AS edges
MATCH (a:Person { name: edges.source})
MATCH (b:Person { name: edges.target })
CREATE (a)-[:HAS_FRIEND]->(b);

The resulting load will say something like:

Created 57 relationships, returned 0 rows in 46 ms

More on exploring and analysing this in a future post.  Tweet it or comment if you are interested in more along this line.  Thanks for reading!

Geospatial Power Tools Reviews [Book]

Thinking of buying my latest book?  We’ve finally got a few reviews on Amazon that might help you decide.  See my other post for more about the book.  Buy the PDF on Locate Press.com.

Reader Reviews

Geospatial Power Tools book cover
From Amazon.com

5.0 out of 5 stars This book makes a great reference manual for using GDAL/OGR suite of command line …,
January 24, 2015 By Leo Hsu
“The GDAL Toolkit is chuckful of ETL commandline tools for working with 100s of spatial (and not so spatial data sources). Sadly the GDAL website only provides the basic API command switches with very few examples to get a user going with. I was really excited when this book was announced and purchased as soon as it came out. This book makes a great reference manual for using GDAL/OGR suite of command line utilities.
Several chapters are devoted to each commandline tool, explaining what its for, the switches it has, and several examples of how to use each one. You’ll learn how to work with both vector/(basic data no vector) data sources and how to convert from one vector format to another. You’ll also learn how to work with raster data and how to transform from one raster data source to another as well as various operations you can perform on these.”


“This is a great book for any GIS pro to get their hands dirty and learn how to use spatial tools to do some amazing things. The benefit of using the tools covered in this book (GDAL/OGR) is that you could learn to integrate these tools into other workflows, such as downloading the latest raster data for your organization on weekly basis and running the necessary tools against it.
The first part of the book is filled with some great examples to get you familiar with using these tools and the rest of the book covers the documentation of these tools in detail. This should be on every GIS pros bookshelf.”


Amazon UK:

5.0 out of 5 stars Absolute Must Have Reference.
14 Feb. 2015 By SamFranklin
“I have been a GDAL/OGR user for about 3 years and have always struggled to find readable, entry-level GDAL documentation that provides simple examples which are well explained. This I feel this is a barrier to greater adoption of GDAL/OGR.
This book 100% fills this gap and is therefore required reading for GDAL novices and veterans alike. The book is split between “Common Tasks & Workflows” and then a comprehensive guide to all utilities. I read it cover to cover and picked a number of ideas and solutions to problems with existing workflows involving GDAL, for that alone, it’s easily worth buying. The first chapter provides links to sample data which is used throughout the book. This allows the reader to replicate every example which is great for learning trickier and lesser known utilities.Cannot recommend highly enough. Great job.”
Thanks for reading, reviewing and for the encouraging comments guys.

Follow me on Twitter and follow Locate Press too for latest sales and deals!  Want to write a book too?  Contact me to discuss.


Graph analytics – the new super power

Graph analytics – is it just hype or is it technology that has come of age?  Mike Hoskins, CTO of Actian sums it up well in this article from InfoWorld:
Mike Hoskins writes about graph analytics and how it is a game changer for finding unknown unknowns
“One area where graph analytics particularly earns its stripes is in data discovery. While most of the discussion around big data has centered on how to answer a particular question or achieve a specific outcome, graph analytics enables us, in many cases, to discover the “unknown unknowns” — to see patterns in the data when we don’t know the right question to ask in the first place.”

Read Mike’s full article at:
InfoWorld

In the remainder of this post I outline a few more of my thoughts on this topic and give you pointers to some more resources to help you understand what to do next.

Finding the unknown unknowns?

You are already familiar with the idea of writing SQL queries to extract data from a database.  Perhaps more recently you even remember having to wrap your head around how to consolidate data from a distributed data store?

But that will only answer your questions.

Say again?  Of course you want answers to your questions, but what about discovering new insights via relationships you didn’t even known existed in your data?  Hence, extracting data with a question you did not anticipate.  For example, you may be looking for edge cases or anomalies that can only be seen when analysing multiple “hops” of a relationships in a network (e.g. friends of friends who like the same music).

Until you try some graph analytics or think through a related problem, you probably won’t really understand the power in these ideas.  In many ways our SQL experience has taught us to not ask some of the harder questions because they weren’t possible to answer with SQL!  I’m speaking from my own personal experience on this and how challenged I was to break out of my previous paradigm.

When SQL is a hammer…

…every data problem that can fit in a table looks like a nail.  However, when a single table is full of a myriad of complex relationships, that’s when things start to get really tricky.  If that data should end up on your Data Analyst’s desk, just wait for the fireworks. That is, unless the DA has graph-like querying tools available.

Let’s look at an example, the many-to-many relationships table.  The table in SQL would just be two columns with names in them, representing a relationship between two people: i.e. Harry, Sally.  Those from the graph world see them as two special subjects with a relationship, not two pieces of text in a table.

These two subjects may have a bidirectional relationship too.  So when doing RDF querying or graph analytics, you will often be building queries to find both relationships: Harry->Knows->Sally and Sally->Knows->Harry.

You can emulate this in SQL with a self join or a second query but don’t bother unless your dataset is really simple and your questions are very superficial as you’ll only get one degree of relationships for each join – then you’ll be tempted to do 20 joins to emulate what can be much easier in a graph analysis engine.

You need graph analytics in the future

“You don’t know my business!”  Yes, but we know what the common data handling needs are for most organisations.  Without fail, companies, governments and non-profits alike all deal with relationship-laden data:

  •  Customers “know” other customers – who are the key influencers in your buying community?
  • Donors support certain kinds of causes and share about them in social media – what other causes are gaining more traction than yours with similar types of donors?
  • Patients have various diagnosis that relate to other patients with similar issues – how can we predict better outcomes if certain factors of care are modified?

How are you planning to deal with such complexity in a proactive way?  Your competitors (and all the Internet titans) are already using it in some way (likely to sell to you better), so it is not going away any time soon.

If you’re just getting started in understanding graph analytics, may I recommend my earlier blog post which is a mini HOWTO using the SPARQLverse analytic engine (from SPARQLcity).  Install it in a couple minutes, push some simple data in and get your hands dirty with the ultra simple example there.

Also, if you don’t know some of the differences between RDF, graph data, SQL and SPARQL, it’s worth digging into.  I’ll leave you with a great article by Robin Bloor on the subject.  He clears the air very well in this article from Inside Analysis, here is a snippet but you should really read the whole thing as it’s very insightful:

“Where the RDF databases really score is when you want to do set processing (a la SQL) at the same time that you want to do graph processing. Consider a query such as “Who are the biggest influencers on Twitter over the past six months?”

Both the RDF and Graph database would handle such a query and return the same results quickly. But if you ask the very different question, “Which influencers have had the same pattern of influence on Twitter over the last six months?” you are asking both for graph processing and set processing at the same time to get to the answer, and the RDF databases do both well. Not only that, but this is an area of analytics, which was virtually untapped until recently, because there was no software that could easily do it.”

Follow me @1tylermitchell for further discussion or see my links in the sidebar.


HP Scanning on OSX Yosemite [SOLVED]

Vuescan website
Vuescan website
It was time to solve my HP scanning problem on OSX Yosemite.  My HP LaserJet CM1312 MFP – multifunction printer is getting a bit old, or at least HP’s support is falling by the wayside. Don’t bother with the HP software as it’s for 10.7. It did work at one point on this laptop but then totally gave up.

I spent too long trying to find new drivers that enable scanning, with no luck, until I found Vuescan.  It’s a free trial (with watermark).  I’m sure it supports lots of scanners, just get it and see before paying.

After a $29 Paypal and 7MB download I was scanning instantly – didn’t even have to point it to my printer.


SPARQL Query for Graph Density Analysis

SPARQLcity Graph Analytics Engine
SPARQLverse is the graph analytics engine produced by SPARQLcity. Standards compliant and super fast!

I’ve been spending a lot of time this past year running queries against the open source SPARQLverse graph analytic engine.  It’s amazing how simple some queries can look and yet how much work is being done behind the scenes.

My current project requires building up a set of query examples that allow typical kinds of graph/network analytics – starting with the kinds of queries needed for Social Network Analysis (SNA), i.e. find friends of friends, graph density and more.

In this post I go through computing graph density in detail.

First of all I’d love to hear what your favourite SPARQL query patterns are in this space.  Please ping/tweet me if you have some that you find yourself using over and over!

My starting point is with some of the samples SPARQLcity makes available on their tips and tricks page.  Let’s first look at a sample dataset and then apply a couple of these to a query problem.

Installing SPARQLverse Graph Analytic Engine

Installing SPARQLverse on a Linux machine is dead simple (you’ll need 8GB RAM by default):

  1. Download latest (binary) release (open source code is available as well!)
  2. Unzip the file
  3. Launch the startup script:
    1. rel/bin/sbxstart
  4. Use web console at http://localhost:8080
  5. Now if you have an RDF/Turtle format triples file you can load it via command line – provide the name of graph to create, and your input filename:
    1. ploadsbx mygraph graph_friends.ttl
      

Sample Turtle Format Data for SPARQL

Don’t be scared away from RDF/Turtle or triple stores in general due to the new format.  Triples don’t get much simpler than just three URIs or even just three distinct words on a line.

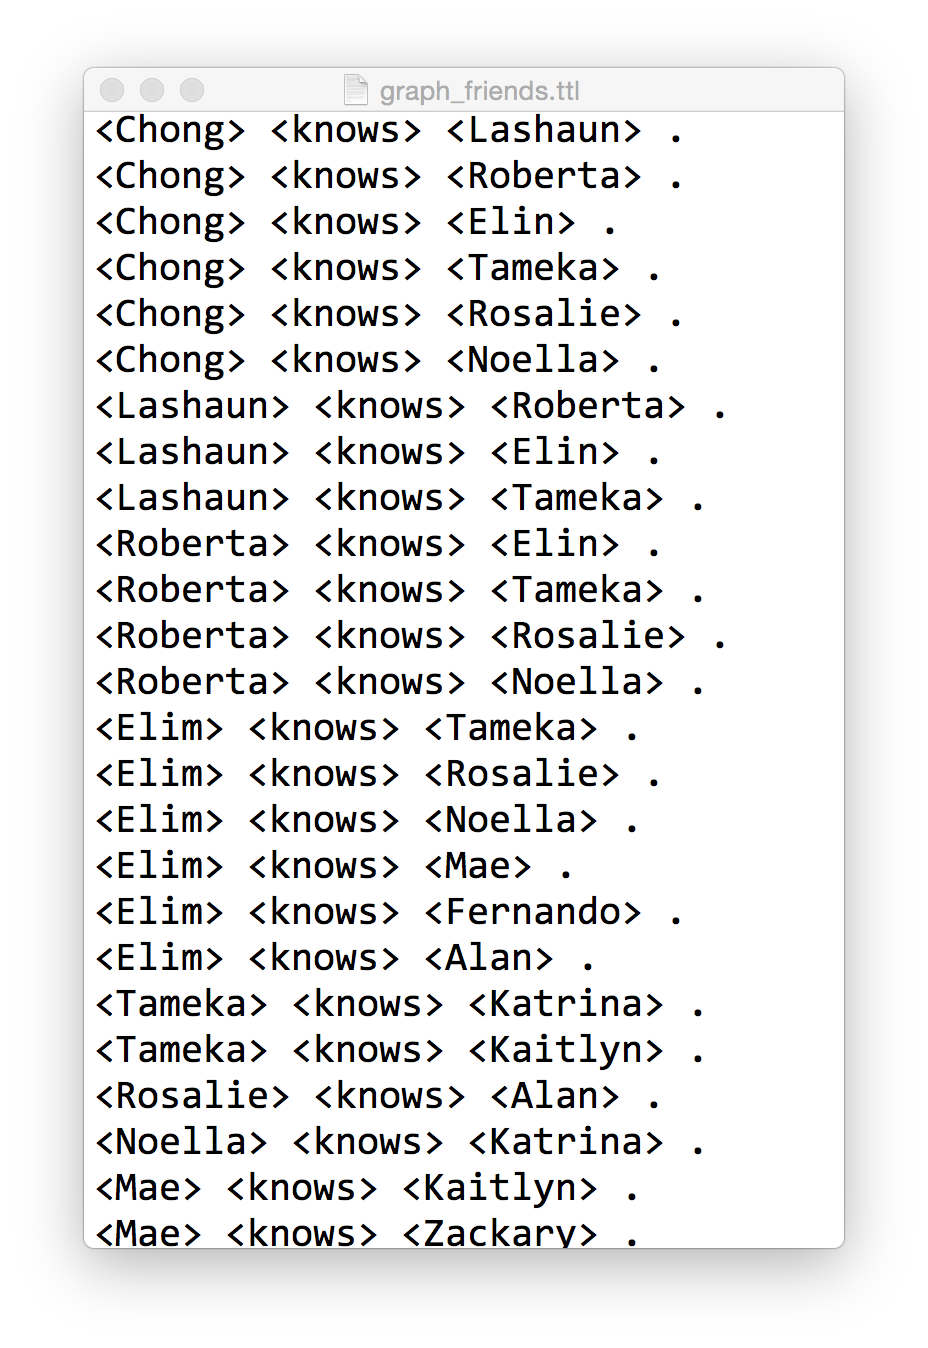
Here is what a sample looks like (graph_friends.ttl) that we can load into SPARQLverse with the above command:

Sample friends graph in Turtle format
Sample friends graph in Turtle format for loading into SPARQLverse graph analytic engine.

It includes 57 specific relationships. The first part of the triple is the Subject, the second is the Predicate/relationship made to the third part, the Object. If you look through the data you’ll see that all the Objects are also defined as Subjects that have other relationships.

Understand the basics here and you’ve got Triples almost mastered.

Note: This is an overly simplistic example, but not totally unrealistic.  We don’t use any URIs but we are allowed to fake them here by simply putting angle brackets around them.  In a linked data environment you’d establish your own namespaces and likely link to external SPARQL endpoints or resources with http:// prefixes.  Now that starts to make your eyes crossed.

Quick Visualisation

As an aside, pull the sample data into Gephi to visualise it and you’ll see the intertwining relationships are not intuitive and would be a challenge to understand using a SQL relational approach.

Friends graph sample viewed in Gephi

What is the Density of the Social Network?

Back to the SPARQL tips page…

What is Graph Density?

Graph density represents how interconnected all entities in the graph are.  They are  a sort of ratio between the total number of connected nodes over maximum number of potential edges.  The value ranges from 0 to 1 – with 0 being a total disconnected graph (not sure if that is technically a graph) with no interconnections between nodes.  And 1 representing a high density graph where all nodes connect to all other nodes.

Here we use a SPARQL query to compute graph density, using the sample dataset above, run from the command line. (Note that I use “?knows” as a predicate when I really want to use “<knows>” but wordpress is not displaying that properly):

$ isbx -c "
 SELECT (?nrEdges/(?nrNodes *(?nrNodes - 1.0)) AS ?graphDensity)
 FROM <graphname>
 WHERE {
  { SELECT (COUNT (*) AS ?nrEdges) (COUNT (DISTINCT ?person) AS ?nrNodes)
    WHERE { ?person ?knows ?anotherPerson . }
   }
 }
"
graphDensity
-------------
0.150000

I changed the example “tips” query to use a different graph name (mygraph) and a different relationship name (knows).  The sub-query in the WHERE clause first counts up the number of edges/relationships and counts the distinct number of nodes as well.  Then the primary query compares that number of edges to nodes.

Let’s break that down into its detail…

Compute the number of unique nodes in the graph

$ isbx -c "SELECT (count (distinct ?person) as ?nrNodes)
> FROM <graphname> WHERE { ?person ?knows ?anotherPerson .}"
nrNodes
--------
20

This tells us that there are 20 people as Subjects in the graph.  Therefore, a maximum number of edges between all people would be 20² (we’ll use only 20×19 as a person might not link to themselves in this example).

Compute the number of edges in the graph

$ isbx -c "SELECT (count (*) as ?nrEdges)
FROM <graphname> WHERE { ?person ?knows ?anotherPerson .}"
nrEdges
--------
57

Total edges is 57.  Do the quick math and see that the ratio is then:

57 / (20 x 19)
= 57 / 380
= 0.149...

Challenge: Inverse Relationships in SPARQL

In some graphs you may not have all the people in the Object position (third part of triple) initialised as Subjects – and their names only show up when someone else defines a relationship to them.

In that case, your density from this query will under-report.  I leave it as an exercise to the reader to figure out how to use SPARQL to do an optional inverse relationship in the sub-query WHERE clause.  Ping me if you want some tips on that.

Future Post

In a future post I’ll walk through some of other graph query examples using SPARQL such as:

  • Who has the most friends who know each other?
  • What is the size of a person’s network?

What else is important to you?  Let me know!


SPARQLverse is part of the Actian Analytics Platform – providing Big Data solutions that are hyper performance with ultimate scalability. Our SQL in Hadoop is the fastest available and runs truly in Hadoop 100%.

Kafka Topic Clearing after Producing Messages

[UPDATE: Check out the Kafka Web Console to more easily administer your Kafka topics]


This week I’ve been working with the Kafka messaging system in a project.

Basic C# Methods for Kafka Producer

To publish to Kafka I built a C# app that uses the Kafka4n libraries – it doesn’t get much simpler than this:

using Kafka.Client;

Connector connector = new Connector(serverAddress, serverPort);
connector.Produce(correlationId, hostName, timeOut, topicName, partitionId, message);

I was reading from various event and performance monitoring logs and pushing them through just fine.

Basic Python Kafka Consumer

For watching the realtime feed, I created a consumer on a Linux machine using the Python kafka-python package:

from kafka import KafkaClient, SimpleConsumer
kafka = KafkaClient("10.0.1.223:6667")

consumer = SimpleConsumer(kafka, "my-group", "winlogs")
for message in consumer:
  print(message)

This worked great until I started pushing in a lot of data both in size and quantity.  Eventually I started getting an error that seems to relate to the max size my consumer could request:

No handlers could be found for logger "kafka"
Traceback (most recent call last):
 File "consume_winlogs.py", line 5, in <module>
 for message in consumer:
 File "/usr/lib/python2.6/site-packages/kafka/consumer.py", line 406, in __iter__
 message = self.get_message(True, timeout)
 File "/usr/lib/python2.6/site-packages/kafka/consumer.py", line 365, in get_message
 return self._get_message(block, timeout, get_partition_info)
 File "/usr/lib/python2.6/site-packages/kafka/consumer.py", line 378, in _get_message
 self._fetch()
 File "/usr/lib/python2.6/site-packages/kafka/consumer.py", line 438, in _fetch
 for message in resp.messages:
 File "/usr/lib/python2.6/site-packages/kafka/protocol.py", line 134, in _decode_message_set_iter
 raise ConsumerFetchSizeTooSmall()
kafka.common.ConsumerFetchSizeTooSmall

So I tweaked my publisher to make sure it wasn’t putting in really large messages (which wasn’t needed for my application anyway) and then cleared the Kafka topic.

Clearing Kafka Topics with Python

After trying a few different approaches to clearing the topic, I found this python approach to be simplest, using the zc.zk module.  First I listed the contents from Zookeeper:

import zc.zk
zk = zc.zk.ZooKeeper('10.0.1.223:2181')
zk.print_tree()

Which showed the topics and consumers that were of interest to me .  I found deleting topics was not enough, I had to also reset the consumer data here so my script would not try to pick up where it left off:

/brokers
 /topics
  /winlogs
...
/consumers
 /my-group
  /offsets
   /winlogs
   /0
    string_value = '1400'

To delete the topic and consumers, it only takes a couple more commands:

zk.delete_recursive('brokers/topics/winlogs')
zk.delete_recursive('consumers/my-group')

Then I started streaming new data back into my topic which will be auto-created.

Increasing Buffer Size

The default buffer size for my Python consumer script was set to some small size that prevents it from getting too many messages.

To fix this I add one more line to my Python consumer script, setting the max buffer size.  See what the default is by getting the value for:

consumer.max_buffer_size

Here I set it to 1Mb and it streams on happily for now, setting it to zero seems to let it go infinitely:

from kafka import KafkaClient, SimpleConsumer
kafka = KafkaClient("10.0.1.223:6667")
consumer = SimpleConsumer(kafka, "my-group2", "winlogs",)
print "Default max buffer size: " + consumer.max_buffer_size
consumer.max_buffer_size=1000000
for message in consumer:
  print(message)

References

  1. Kafka messaging system: https://kafka.apache.org/
  2. Kafka4n .NET client: https://github.com/miknil/Kafka4n
  3. Kafka-python module: https://pypi.python.org/pypi/kafka-python/0.9.2
  4. Python Zookeeper module: https://pypi.python.org/pypi/zc.zk

Social Graph – Year in Review (Preparation)

Graph developed from Tyler Mitchell's LinkedIn connections.

I pulled this visualization of my LinkedIn social graph together in just a few minutes while working through a tutorial.  What about other social networks?  Give me your input…

I’m picking away at an article reviewing the various ways to access your own, personal, social graph data from the various sources out there.

Wow, what a mixture of results are available through the different APIs that are exposed.  Some good and some bad – some really bad!  I’m especially interested in assessing how many “walled gardens” got taller or shorter walls this year.

Your Social Graph Projects?

I’d like to add your input to my research.  If you have:

  • built an app that leverages social network graph data to identify relationships
  • run social network or graph analytics on such data, or
  • just generally worked with APIs from Twitter, Google+, LinkedIn, Facebook (or others)

… I’d like to hear from you.  What information could you not get access to?  What information was easiest to come by?  Were some barriers insurmountable?

I’ll be completing my article, with both high level and technical “how to” reviews, later this year.

Please comment here or drop me a note.

Data Sharing Saved My Life – or How an Insurer Reduced My Healthcare Claim Costs

It’s not every day that you receive snail mail with life-changing information in it, but when it does come, it can come from the unlikeliest sources.

Healthcare data shown in a list of bio sample test results
My initial test results showing problems with the Liver

A year ago, when doing a simple change of health insurance vendors, I had to give the requisite blood sample.  I knew the drill… nurse comes to the house, takes blood, a month later I get new insurance documents in the mail.

But this time the package included something new: the results of my tests.

The report was a list of 13 metrics and their values, including a brief description about what they meant and what my scores should be.  One in particular was out of the norm.  My ALT score, which helps measure liver malfunction, was about 50% higher than the expected range.

Simple Data Can Be Valuable

Here is the key point: I then followed up with my family doctor, with data in hand.  I did not have to wait to see symptoms of a systemic issue and get him to figure it out. We had a number, right there, in black and white. Something was wrong.

Naturally, I had a follow up test to see if it was just a blip.  However, my second test showed even worse results, twice as high in fact!  This lead to an ultrasound and more follow up tests.

In the end, I had (non-alcoholic) Fatty Liver Disease.  Most commonly seen in alcoholics, it was a surprise as I don’t drink.  It was solely due to my diet and the weight I had put on over several years.

It was a breaking point for my system and the data was a big red flag calling me to change before it was too late.

Wellness FX chart of ALT
A chart showing some of my earlier tests – loaded into WellnessFX.com for visualisation.

Not impressed with my weight nor all my other scores, I made simple but dramatic changes to improve my health.*  Changes were so dramatic that my healthcare provider was very curious about my methods.

By only making changes to my diet I was able to get my numbers to a healthy level in just a few months.  In the process I lost 46 pounds in 8 months and recovered from various other symptoms.  The pending train wreck is over.

Long Term Value in Sharing Healthcare Data

It’s been one year this week, so I’m celebrating and it is thanks to Manulife or whoever does their lab tests, for taking the initiative to send me my lab results.

It doesn’t take long to see the business value in doing so, does it?   I took action on the information and now I’m healthier than I have been in almost 20 years.  I have fewer health issues, will use their systems less, will cost them less money, etc.

Ideally it benefits the group plan I’m in too as a lower cost user of the system.  I hope both insurers and employers take this to heart and follow suit to give the data their people need to make life changing and cost reducing decisions like this.

One final thought.. how many people are taking these tests right now?  Just imagine what you could do with a bit of data analysis of their results.  Taking these types of test results, companies could be making health predictions for their customers and health professionals to review.  That’s why I’m jumping onto “biohacking” sites like WellnessFX.com to track all my scores these days and to get expert advice on next steps or access to additional services.

I’m so happy with any data sharing, but why give me just the raw data when I still have to interpret it?  I took some initiative to act on the results, but what if I had needed more incentive?  If I had been told “Lower your ALT or your premiums will be 5% higher” I would have appreciated that.

What’s your price?  If your doctor or insurer said “do this and save $100” – would you do it?  What if they laid the data out before you and showed you where your quality of life was headed, would it make a difference to you?

I’m glad I had this opportunity to improve my health, but at this point I just say thanks for the data … and pass the salad please!

Tyler


* I transitioned to a Whole Food – Plant Based diet (read Eat to Live and The China Study).  You can read more about the massive amounts of nutrition science coming out every year at NutritionFacts.org or read research papers yourself.

HBase queries from Bash – a couple simple REST examples

Learn how to do some simple queries to extract data from the Hadoop/HDFS based HBase database using its REST API.

Are you getting stuck trying to figure out HBase query via the REST API?  Me too.  The main HBase docs are pretty limited in terms of examples but I guess it’s all there, just not that easy for new users to understand.

As an aside, during my searches for help I also wanted to apply filters – if you’re interested in HBase filters, you’ll want to check out Marc’s examples here.

What docs do you find most useful?  Leave a comment.  Should someone write more books or something else?

My Use Cases

There were two things I wanted to do – query HBase via REST to see if a table exists (before running the rest of my script, for example).  Then I wanted to grab the latest timestamp from that table.  Here we go…

Does a specific table exist in HBase?

First, checking if a table exists can be done in a couple ways.  The simplest is to simply request the table name with the “exists” path after it and see what result you get back.

$ curl -i http://localhost/existing_table/exists

HTTP/1.1 200 OK
Cache-Control: no-cache
Content-Type: text/plain
Content-Length: 0

$ curl -i http://localhost/bad_table_name/exists
HTTP/1.1 404 Not Found
Content-Length: 11
Content-Type: text/plain

Not found

Here I use the curl “-i” option to return the detailed info/headers so I can see the HTTP responses (200 vs 404).  The plain text results from the command are either blank (if exists) or “Not found” if it does not.

Let’s roll it into a simple Bash script and use a wildcard search to see if the negative status is found:

CMD=$(curl http://localhost/table_name/exists)

if [[ $CMD = *"Not found"* ]]
 then echo "Not found"
else 
 echo "Found"
fi

Extract a timestamp from an HBase scanner/query

Now that I know the table exists, I want to get the latest timestamp value from it.  I thought I’d need to use some filter attributes like I do in HBase shell:

scan 'existing_table', {LIMIT=>1}

To do this with curl, you want to use HBase scanner techniques to accomplish this (the shortest section in the official docs it seems).

It’s a two stage operation – first you initialise a scanner session, then you request the results.  Bash can obviously help pull the results together easily for you, but let’s so go step by step:

curl -vi -H "Content-Type: text/xml" -d '<Scanner batch="1"/>' "http://localhost/existing_table/scanner"

...
Location: http://localhost/existing_table/scanner/12120861925604d3b6cf3
...

Note the XML chunk in the statement that tells it how many records to return in the batch.  That’s as simple as it gets here!

Amongst the results of this command you’ll see the Location value returned, this is the URL to use to access the results of the query.  Results are truncated and line breaked so you can see the meaningful bits:

$ curl http://localhost/existing_table/scanner/12120861925604d3b6cf3

<?xml version="1.0" encoding="UTF-8" standalone="yes"?>
 <CellSet>
  <Row key="AfrV65UNXD0AAAAs">
   <Cell column="ZXZ...mNl" 
    timestamp="1218065508852">
    L2hv...Y3N2
   </Cell>
  </Row>
 </CellSet>

Ugh, XML.. if you want JSON instead just add an ACCEPT property to the header:

$ curl -H "Accept: application/json" http://localhost/existing_table/scanner/12120861925604d3b6cf3

{"Row":[{"key":"AfrV65UNXD0AAAAs","Cell":[{"column":"ZXZ...mnl","timestamp":1218065508852,"$":"L2hv...Y3N2"}]}
...

For now we’ll hack some sed to get the to the value we want, first for the JSON response, second for the XML response.  Just pipe the curl command into this sed:

# For application/json
$ curl ... | sed 's/.*\"timestamp\"\:\([0-9]\{13\}\).*/\1/'

# For default XML results
$ curl ... | sed 's/.*timestamp=\"\([0-9]\{13\}\).*/\1/'

Now you can create a basic script the grabs the latest timestamp from the HBase query and decides what to do with it.  Here we just assign it to a variable and let you go back to implement as needed.

$ LAST_TIME=$(curl ... | sed 's/.*\"timestamp\"\:\([0-9]\{13\}\).*/\1/')
$ echo $LAST_TIME

1218065508858

Thanks for reading!

If you like this, follow me on Twitter at http://twitter.com/1tylermitchell or with any of the other methods below.


WordPress Appliance - Powered by TurnKey Linux